Core Foundation
Hardware & Platform Foundation
Infrastructure for the agent ecosystem — local compute, absolute privacy, peak performance
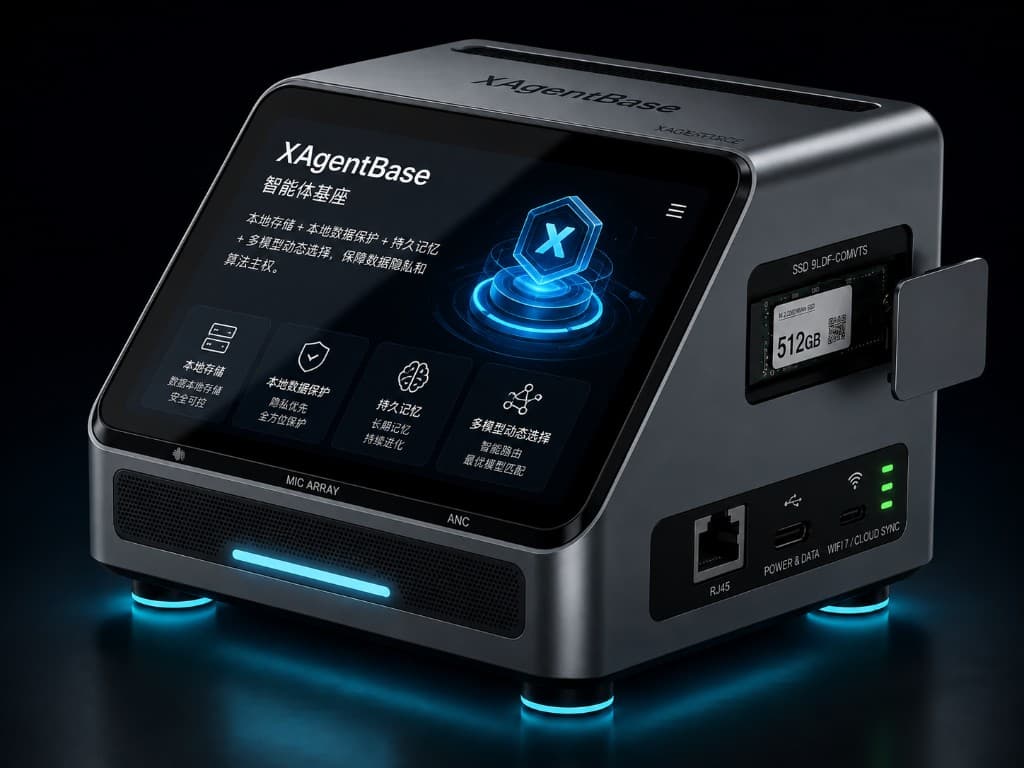
XAgentBase
Hardware Agent Foundation of XAgentForce
All XAgent vertical agents are built on this foundation:
Local data storage + local data protection + persistent memory + dynamic multi-model selection, protecting data privacy and algorithm sovereignty.
Compute Editions
100% on-device inference — models, memory, and private data never leave your hardware.
Edge AI Compute
On-device NPU + GPU acceleration for local LLM & multi-agent inference
Unified Memory
High-bandwidth LPDDR5 unified memory for concurrent on-device models
Local Model Vault
NVMe SSD for models, knowledge base, and encrypted private data
Edge Runtime
Hardened Linux edge OS — always-on agents, OTA-ready
› route → TurboCore.schedule(batch)
› kv_cache.warm(tokens=2048)
› latency.p50 = 42ms · p99 = 96ms
› ModelSwitch.pick([qwen, deepseek, glm])
› desensitize(local) → edge.infer()
› speculative.accept(ratio=0.71)
› stream.emit(delta) · tokens/s ↑
› health.check() → ok · ota=idle
› route → TurboCore.schedule(batch)
› kv_cache.warm(tokens=2048)
› latency.p50 = 42ms · p99 = 96ms
› ModelSwitch.pick([qwen, deepseek, glm])
› desensitize(local) → edge.infer()
› speculative.accept(ratio=0.71)
› stream.emit(delta) · tokens/s ↑
› health.check() → ok · ota=idle
TurboCore Inference Acceleration Engine
Edge–cloud synergy for faster AI inference, lower latency, and stronger data security.
Technology
Edge-cloud synergy · Speculative sampling · KV Cache hardware optimization
Key Metrics
50%+ token savings · First-token latency <100ms · 2–3× inference speedup; raw data is also desensitized and preprocessed to protect user privacy.
ModelSwitch Multi-Model Intelligent Scheduling Engine
Match every AI call with a more suitable model.
Technology
Smart routing · Cost optimization · Failover · Load balancing
Key Metrics
Dynamic switching across Volcano, Qwen, Kimi, GLM, DeepSeek, MiniMax, MiMo, and more
› route → TurboCore.schedule(batch)
› kv_cache.warm(tokens=2048)
› latency.p50 = 42ms · p99 = 96ms
› ModelSwitch.pick([qwen, deepseek, glm])
› desensitize(local) → edge.infer()
› speculative.accept(ratio=0.71)
› stream.emit(delta) · tokens/s ↑
› health.check() → ok · ota=idle
› route → TurboCore.schedule(batch)
› kv_cache.warm(tokens=2048)
› latency.p50 = 42ms · p99 = 96ms
› ModelSwitch.pick([qwen, deepseek, glm])
› desensitize(local) → edge.infer()
› speculative.accept(ratio=0.71)
› stream.emit(delta) · tokens/s ↑
› health.check() → ok · ota=idle
Standard Edition · Built-in Skills
PDF Reading
Text-based and image-based PDFs
Word Reading
.docx / .doc
Excel Reading
.xlsx / .xls, multi-sheet support
PPT Reading
.pptx / .ppt
Image OCR
Chinese & English mixed layout · JPG/PNG/GIF/WebP
Real-time Web Search
News, weather, stock prices, and more
Email Sending
SMTP with attachments and scheduled delivery
Local Knowledge Base
Semantic search + RAG Q&A (continuously improving)
System Self-check
Version/status detection + auto-repair
Over-the-Air Updates
OTA remote upgrades
Six High-Frequency Application Scenarios
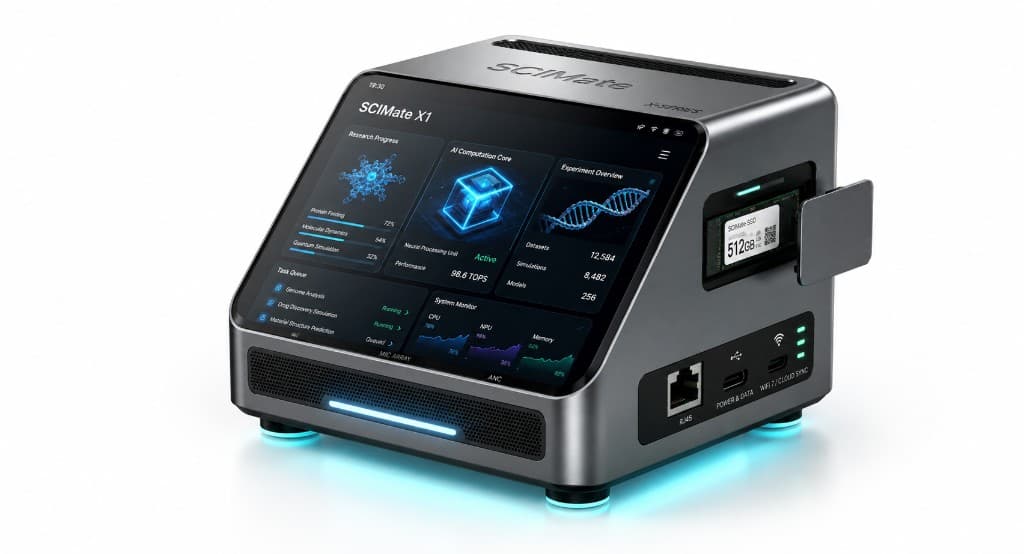
Information Gathering & Synthesis
Best For
Researchers, content operators, early risers
Core Value
Finish in half an hour what used to take days
Ecosystem
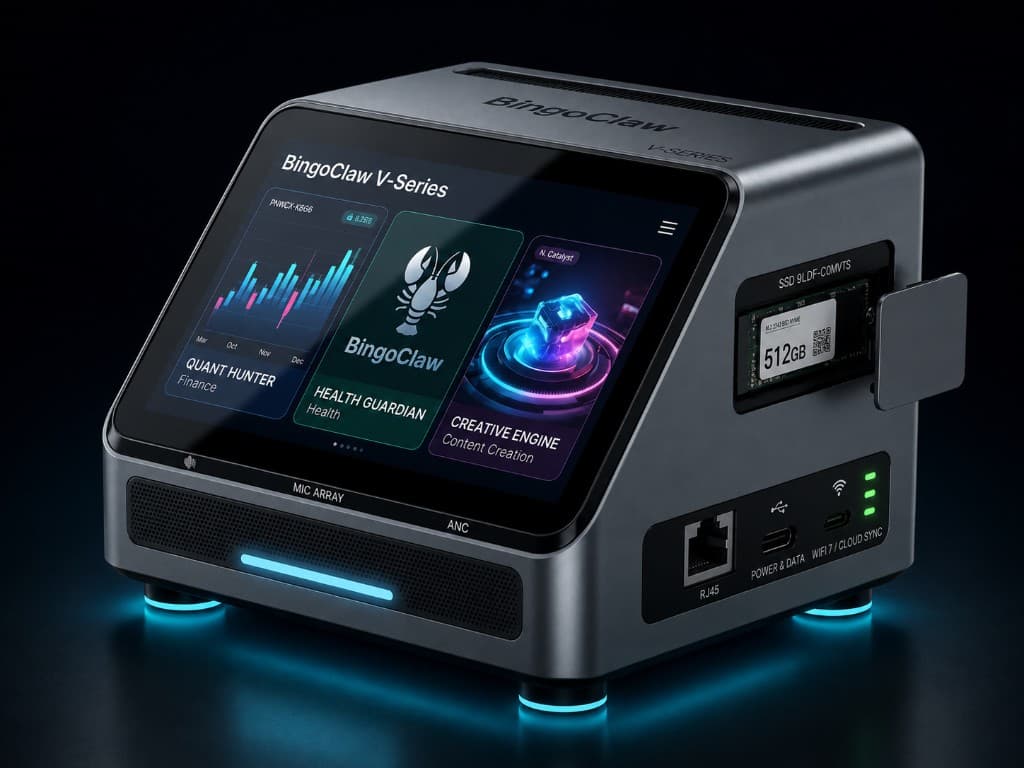
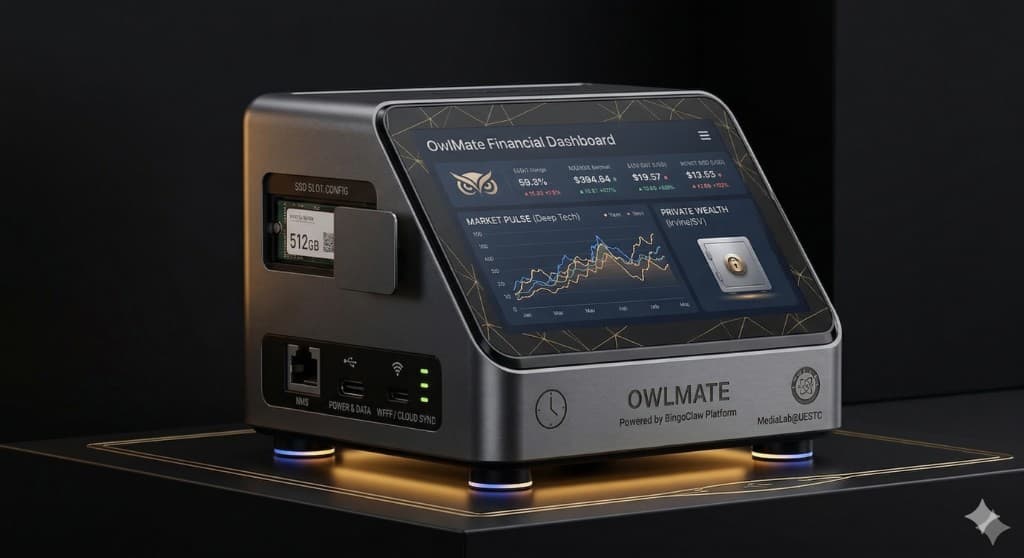
Agent Ecosystem Matrix
Full-stack digital life products spanning professional, consumer, and productivity scenarios
Professional Suite
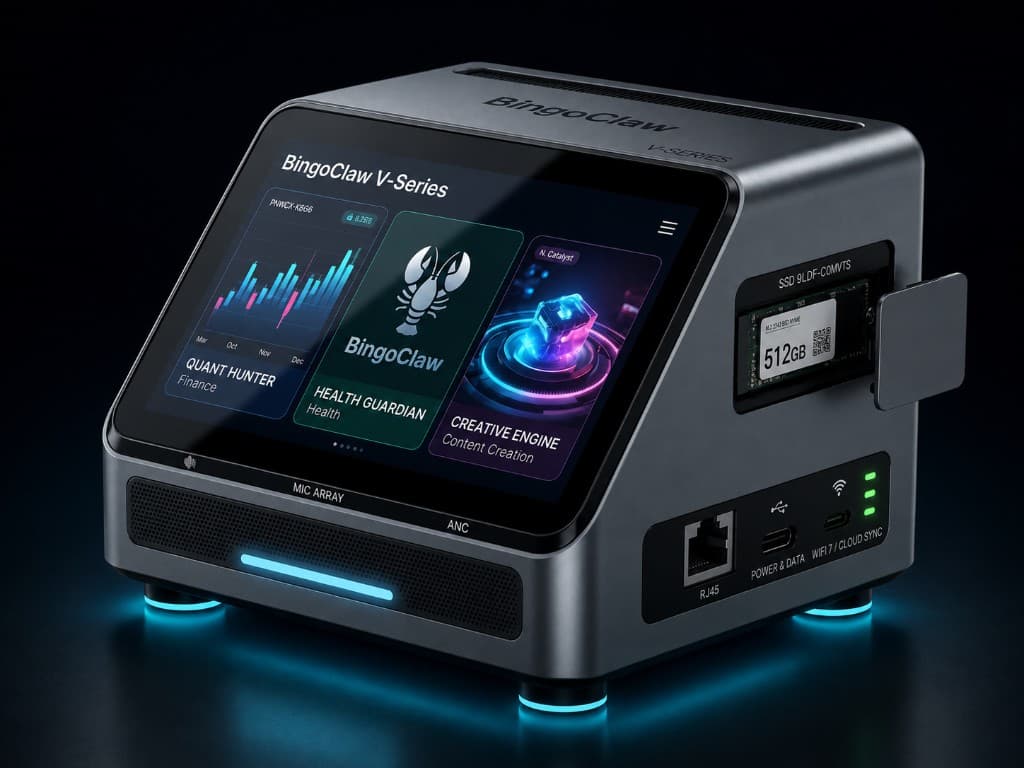
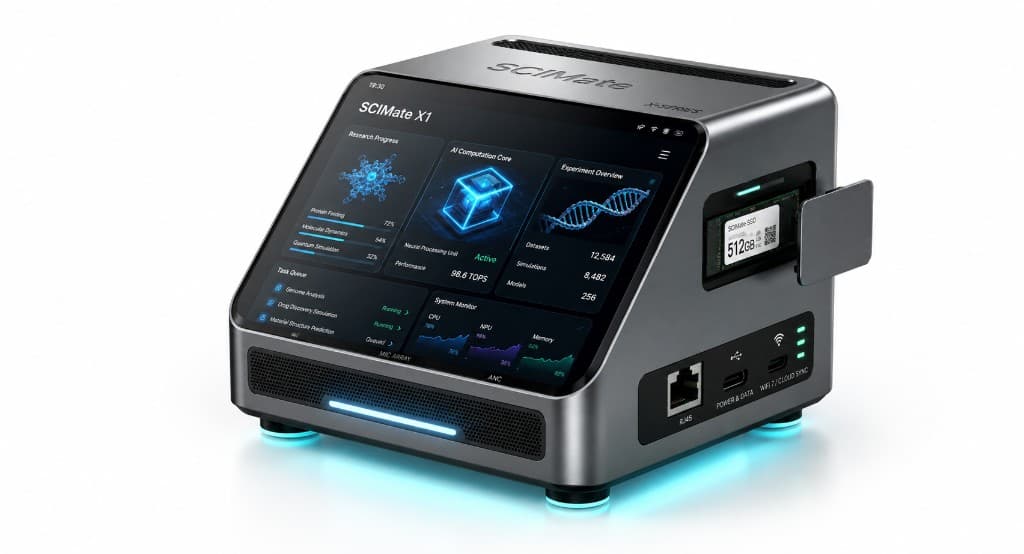
Personal agents · Professional domains · Vertical depth
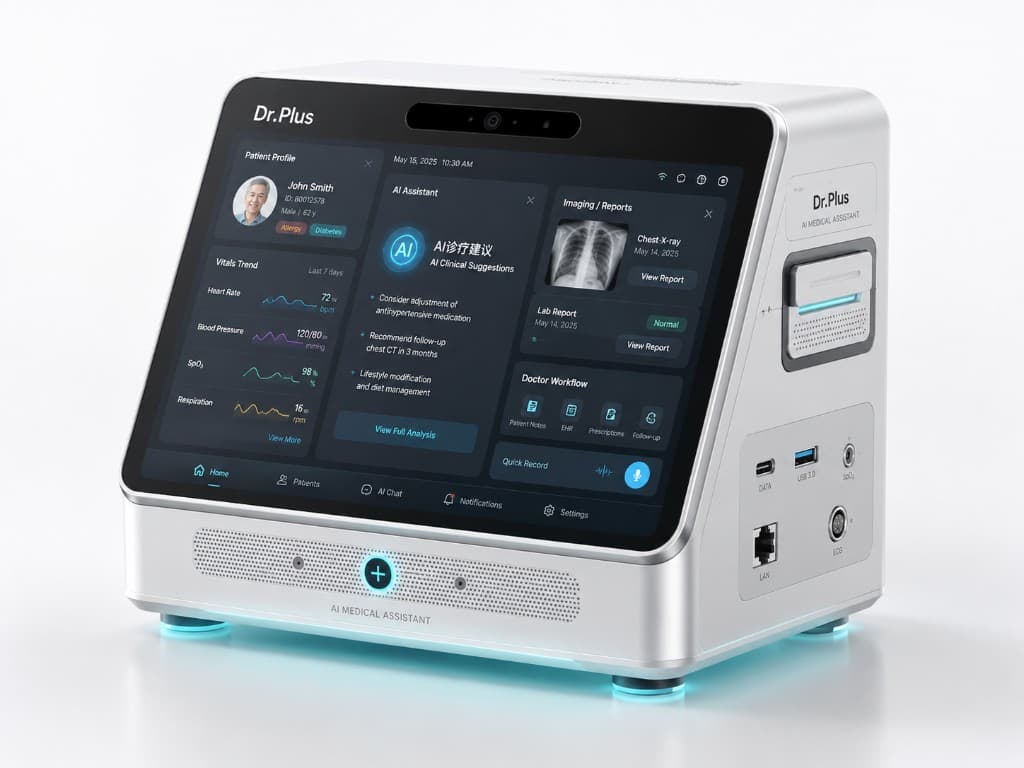
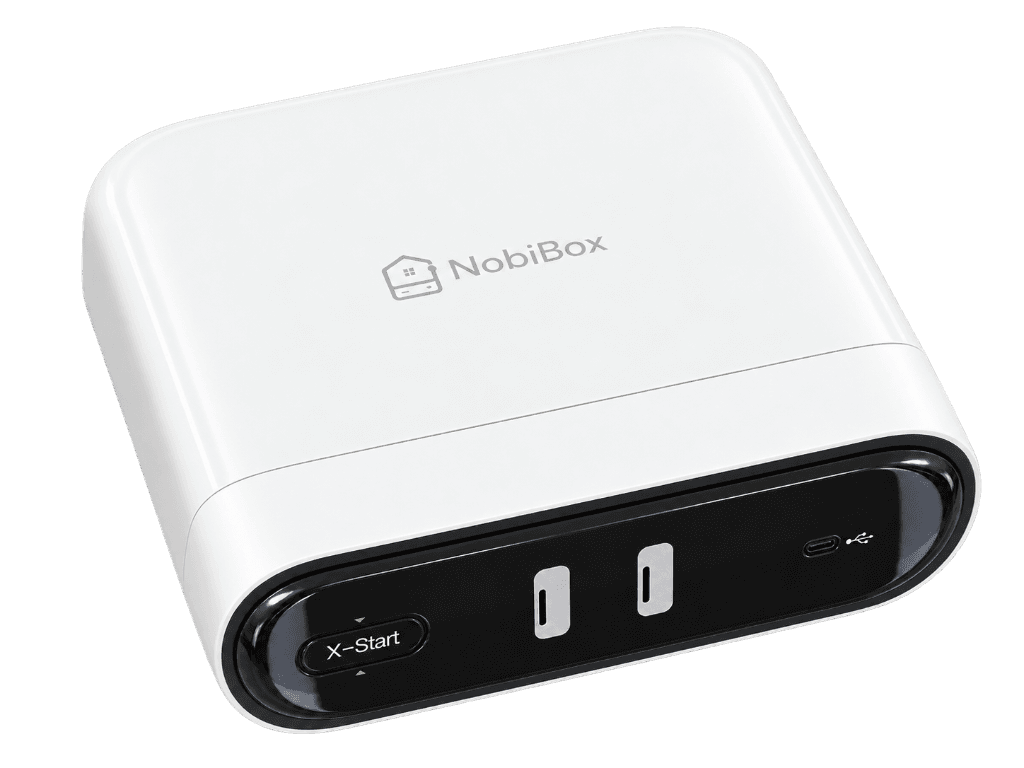
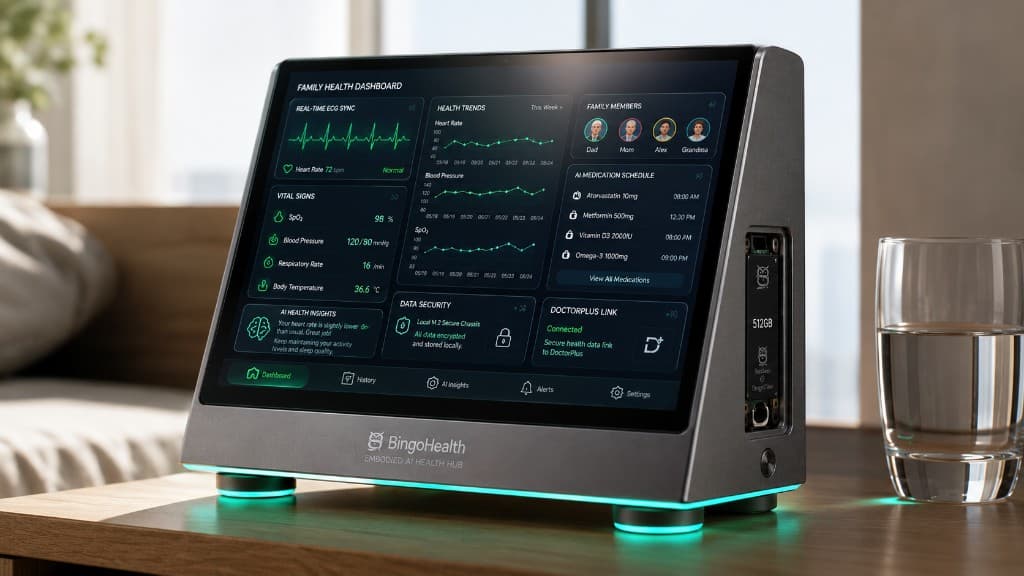
Health & Home
Home hub · Personal health · Local AI guardian
Consumer & Productivity Suite
Consumer & productivity · Digital companions for everyone